Benchmarks
Every chart on this page is generated, not hand-drawn: benchmarks/plot_comparison.py reads
pytest-benchmark's own --benchmark-json output (via benchmarks/aggregate.py, the same module
that produces the plain-text loss tables used during development) and renders one pair of PNGs per
comparison, each competing library named by its own logo. Nothing here is cherry-picked in the
sense of hiding a loss — the six cells below were chosen for being visually clean and for spanning
different areas of the library (topology, discrete differential geometry, geodesics, editing,
point-cloud reconstruction, measures), and the raw numbers next to each chart are exactly what the
benchmark suite produced.
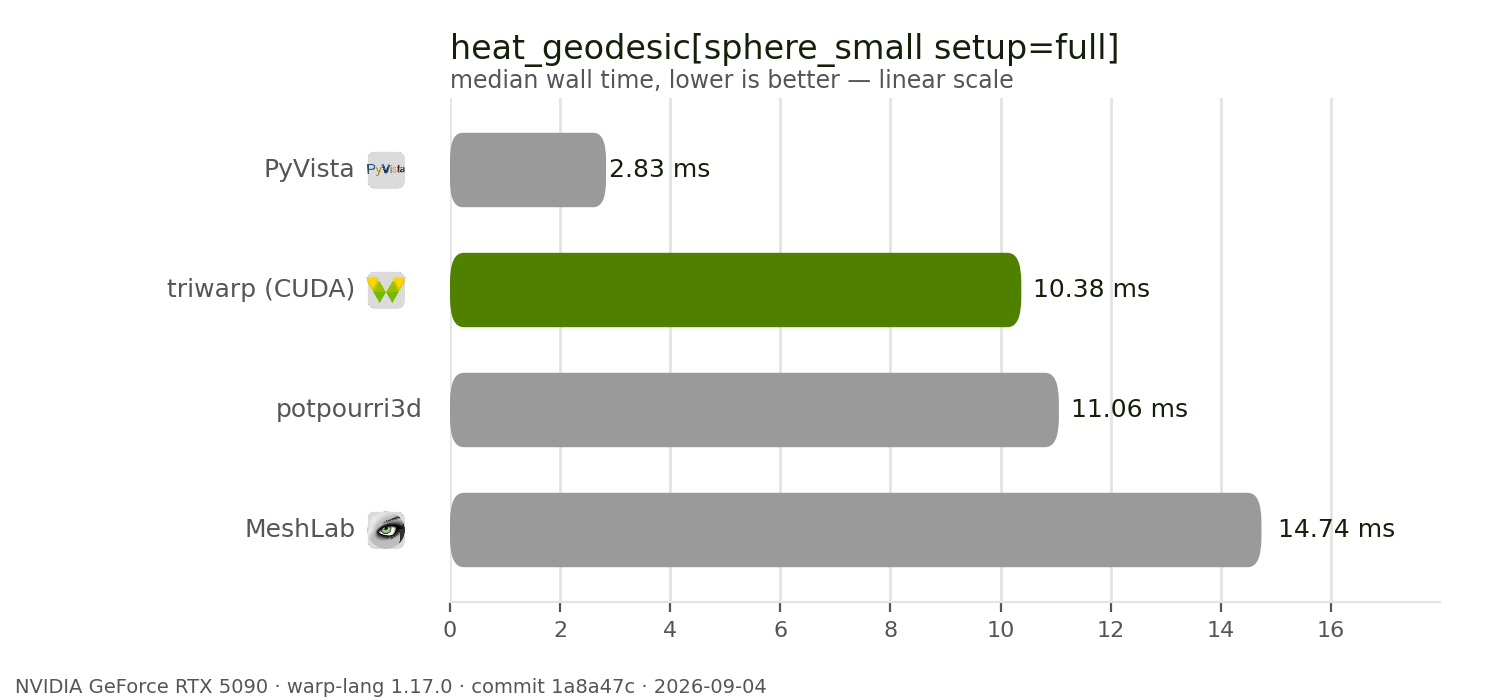
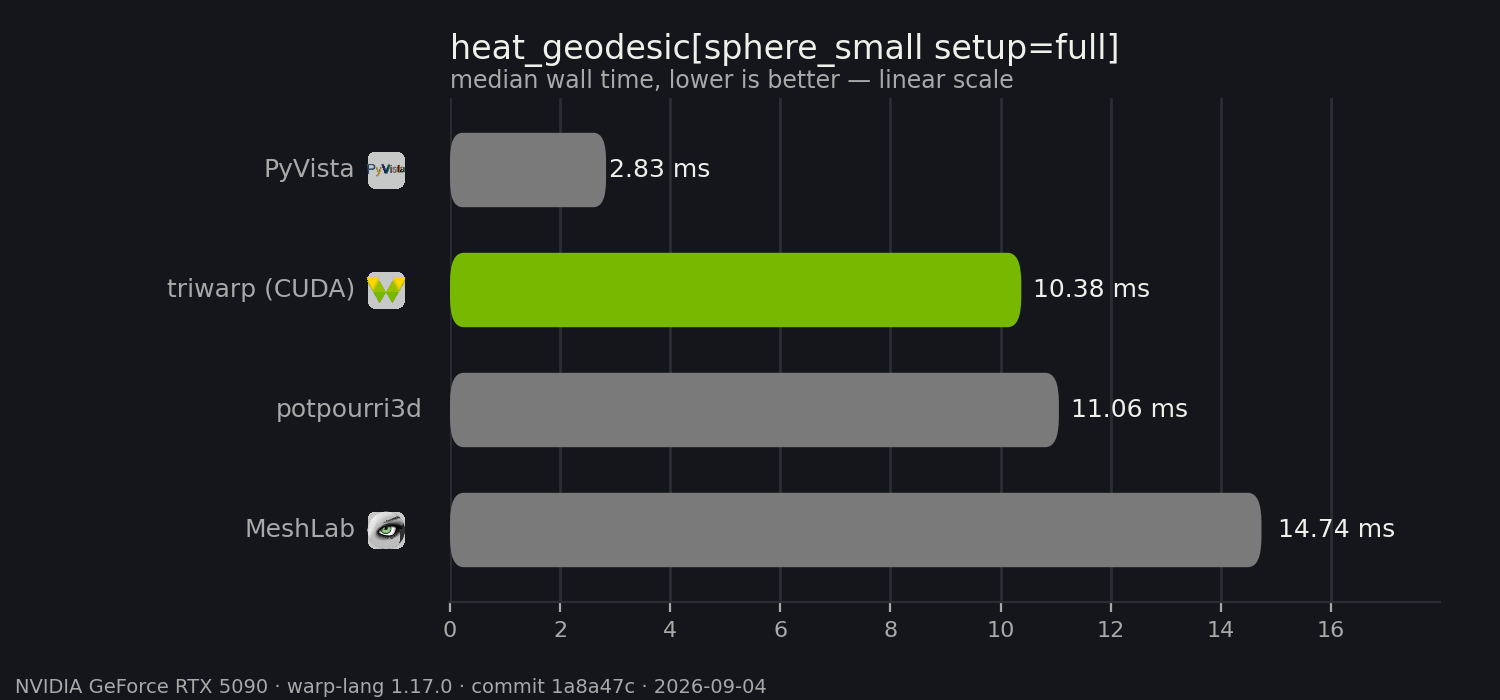
How to read one of these: bars are sorted fastest-to-slowest, top to bottom; triwarp's own bar is the accent color, every reference library is the same muted gray (the logo and label carry which library it is — color is reserved for "is this triwarp"); the axis switches to a log scale whenever the fastest and slowest library in that cell differ by more than 15x, stated in the chart's own subtitle so it is never ambiguous; and every bar carries its exact value as a direct label, so nothing depends on reading the axis precisely.
Reproduce any of these yourself:
git clone https://github.com/lucagrementieri/triwarp
cd triwarp
uv sync --group bench
uv run pytest benchmarks/ --benchmark-json=path/to/one.json   # or per-module, one file each
uv run python benchmarks/plot_comparison.py path/to/json_dir --out /tmp/charts --hero
See benchmarks/README.md for
the full methodology — which axis each group sweeps, which libraries are compared for which
operation, and why a handful of comparisons are excluded.
Topology: faces_to_edges
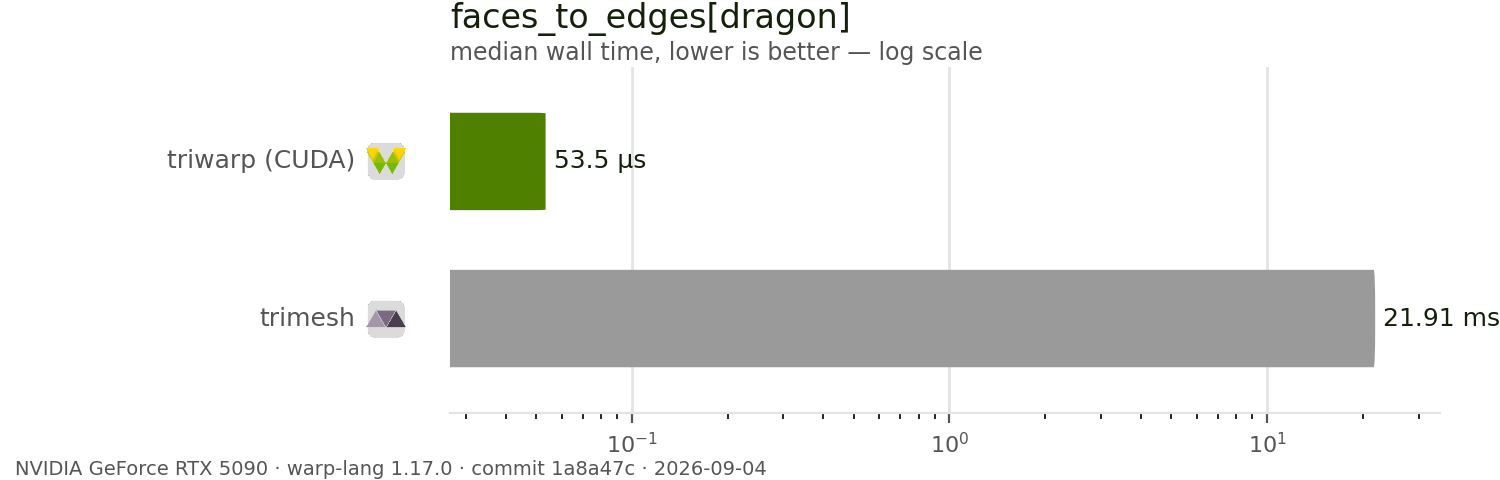
Exact values
| Library | Median |
|---|---|
| triwarp (CUDA) | 53.5 µs |
| trimesh | 21.91 ms |
Discrete differential geometry: cotmatrix
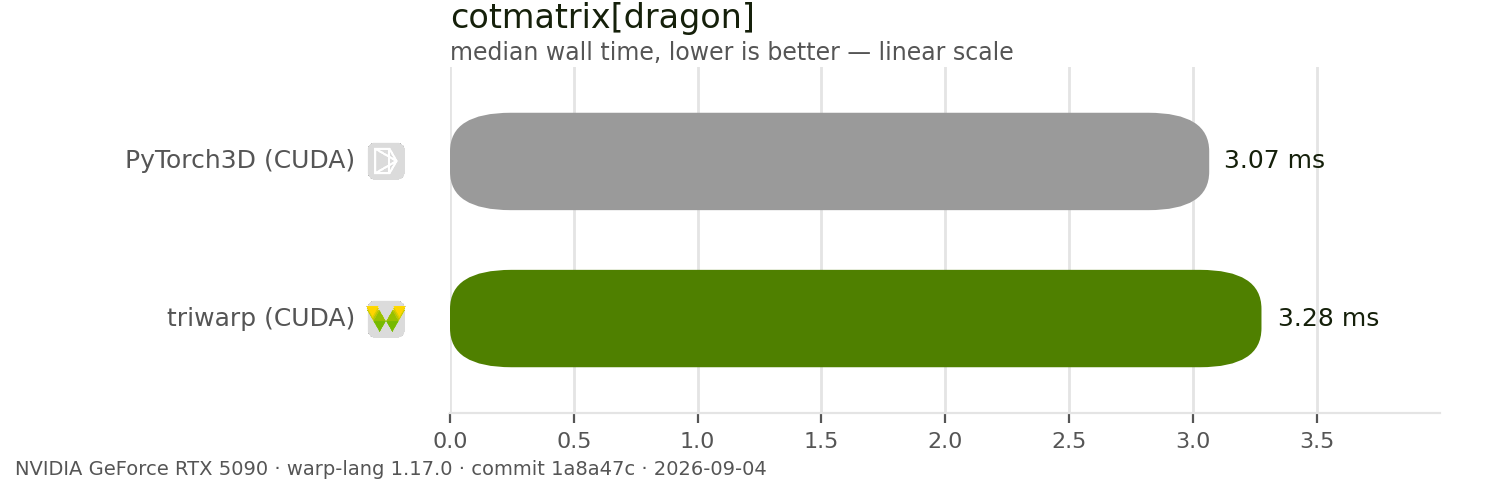
Exact values
| Library | Median |
|---|---|
| PyTorch3D (CUDA) | 3.07 ms |
| triwarp (CUDA) | 3.28 ms |
Read this one with its caveat, not just its number: PyTorch3D's cot_laplacian returns an
uncoalesced sparse tensor with duplicate entries and no assembled diagonal, where triwarp's
cotmatrix returns a fully assembled, deduplicated CSR matrix — so this is the raw comparison,
and it is genuinely closer than it looks once both sides do the same amount of work (see
Migrating from PyTorch3D for the full explanation). Shown as
measured, caveat and all, rather than adjusted to flatter either side.
Geodesics: heat_geodesic
Exact values
| Library | Median |
|---|---|
| PyVista | 2.83 ms |
| triwarp (CUDA) | 10.38 ms |
| potpourri3d | 11.06 ms |
| MeshLab | 14.74 ms |
Editing: quadric_decimate
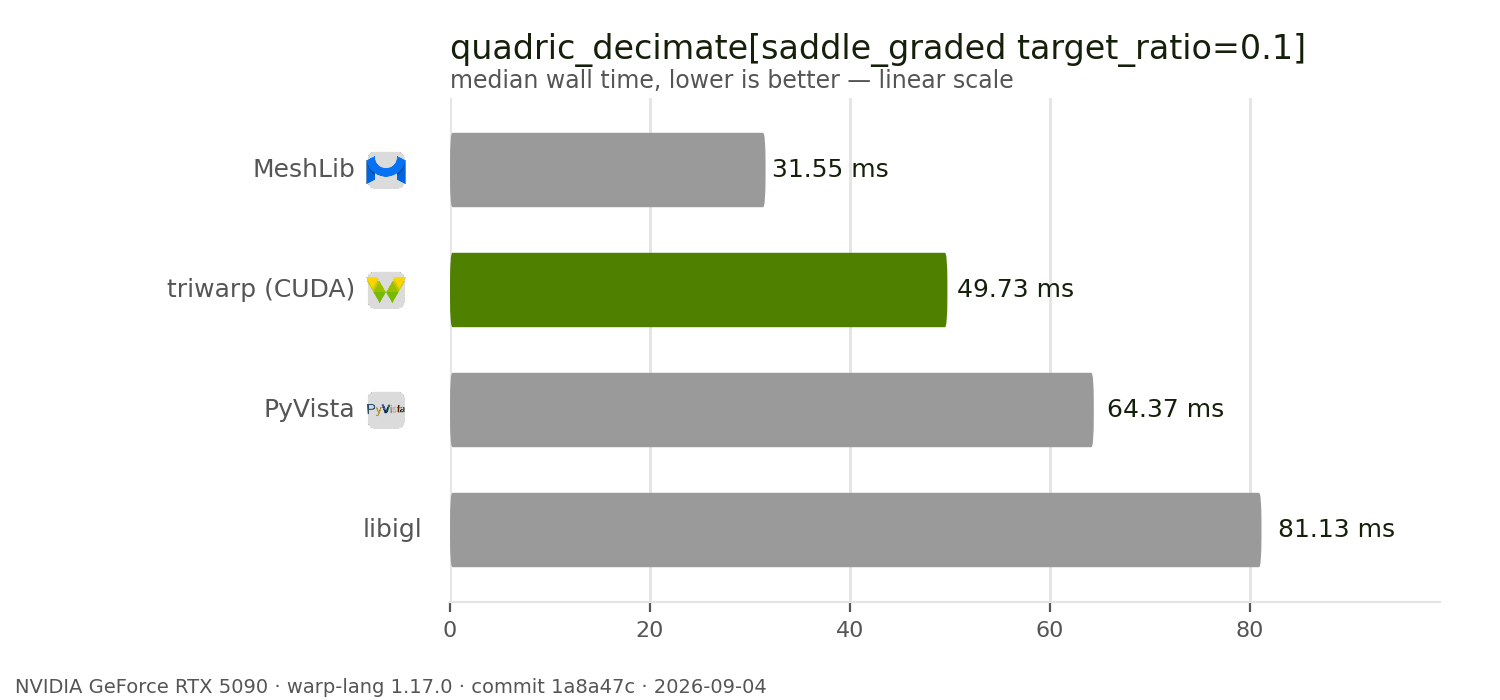
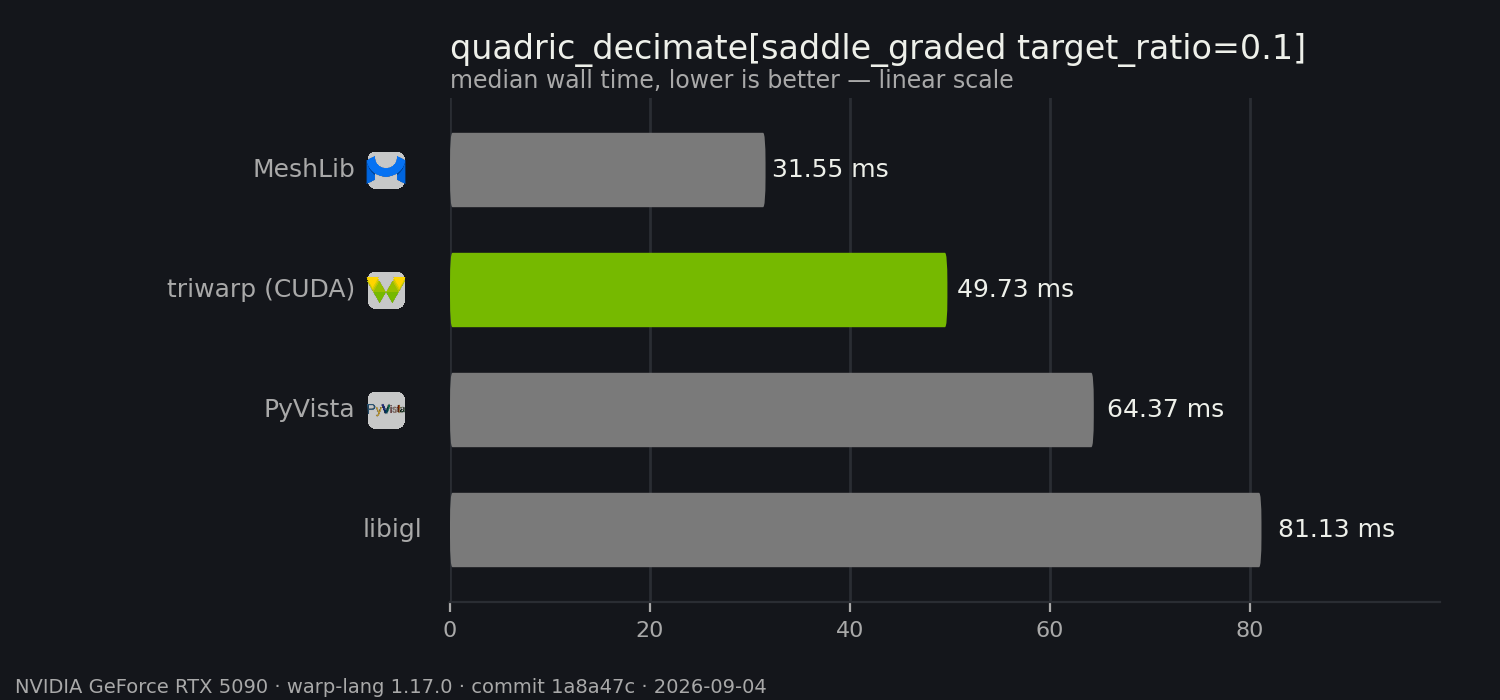
This is also an honest loss: MeshLib's serial C++ decimator is faster than triwarp's on this particular (small, graded) mesh — triwarp's GPU decimator wins by a wide margin at larger mesh sizes, where there is enough parallelism to fill the device, but the crossover is real and this chart doesn't hide which side of it a small input lands on.
Exact values
| Library | Median |
|---|---|
| MeshLib | 31.55 ms |
| triwarp (CUDA) | 49.73 ms |
| PyVista | 64.37 ms |
| libigl | 81.13 ms |
Point-cloud reconstruction: ball_pivoting
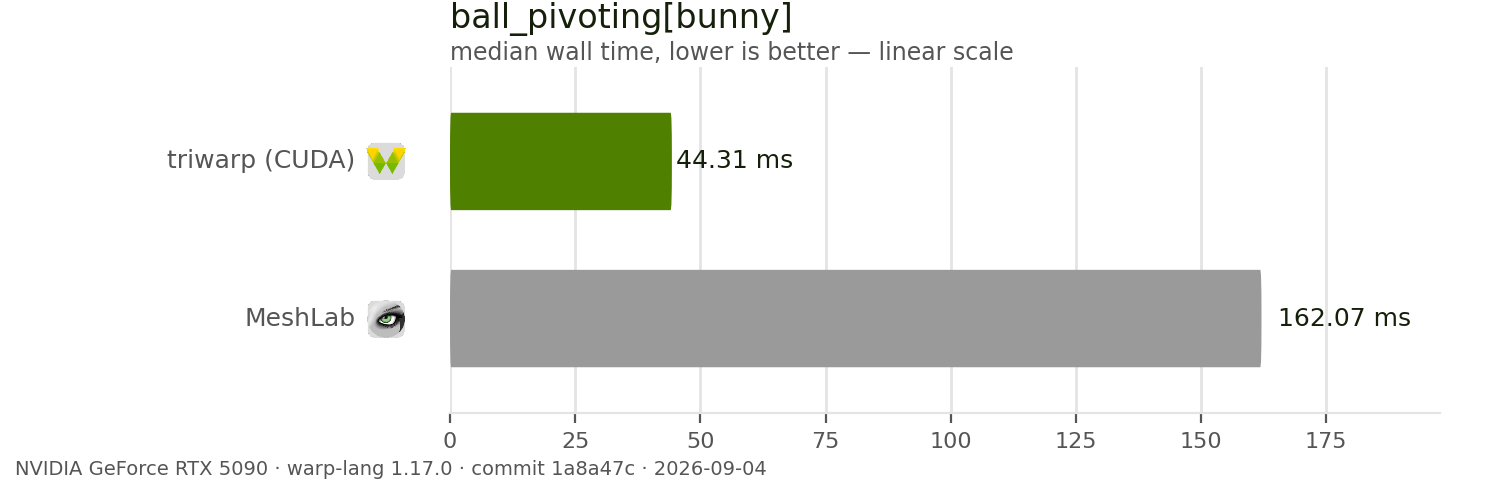
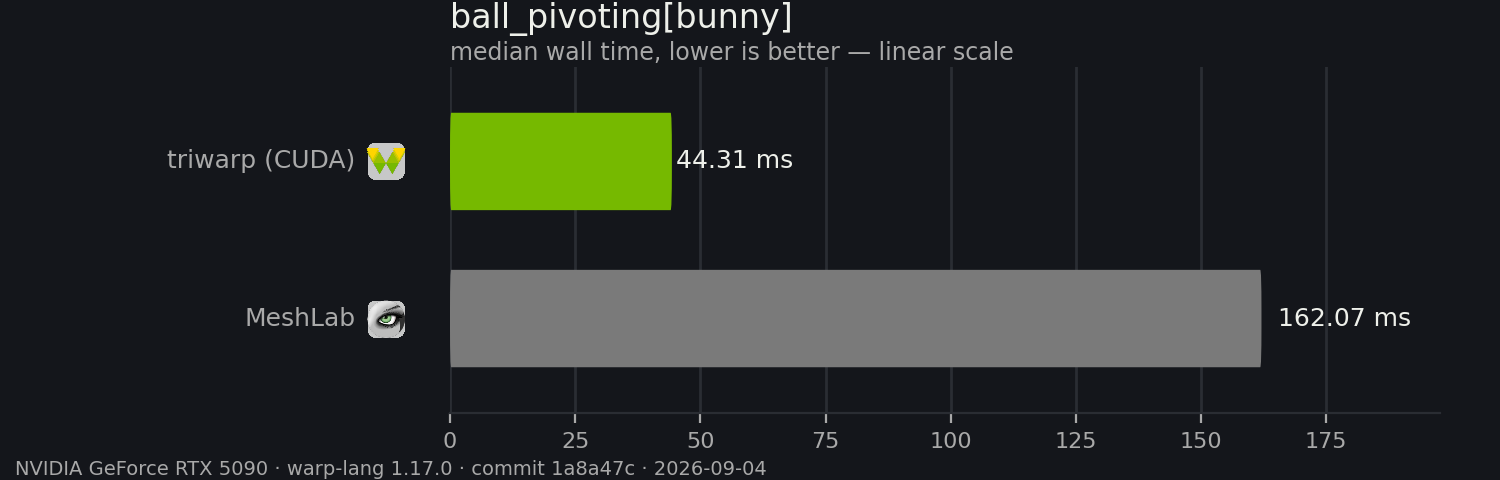
Exact values
| Library | Median |
|---|---|
| triwarp (CUDA) | 44.31 ms |
| MeshLab | 162.07 ms |
Measures: aabb
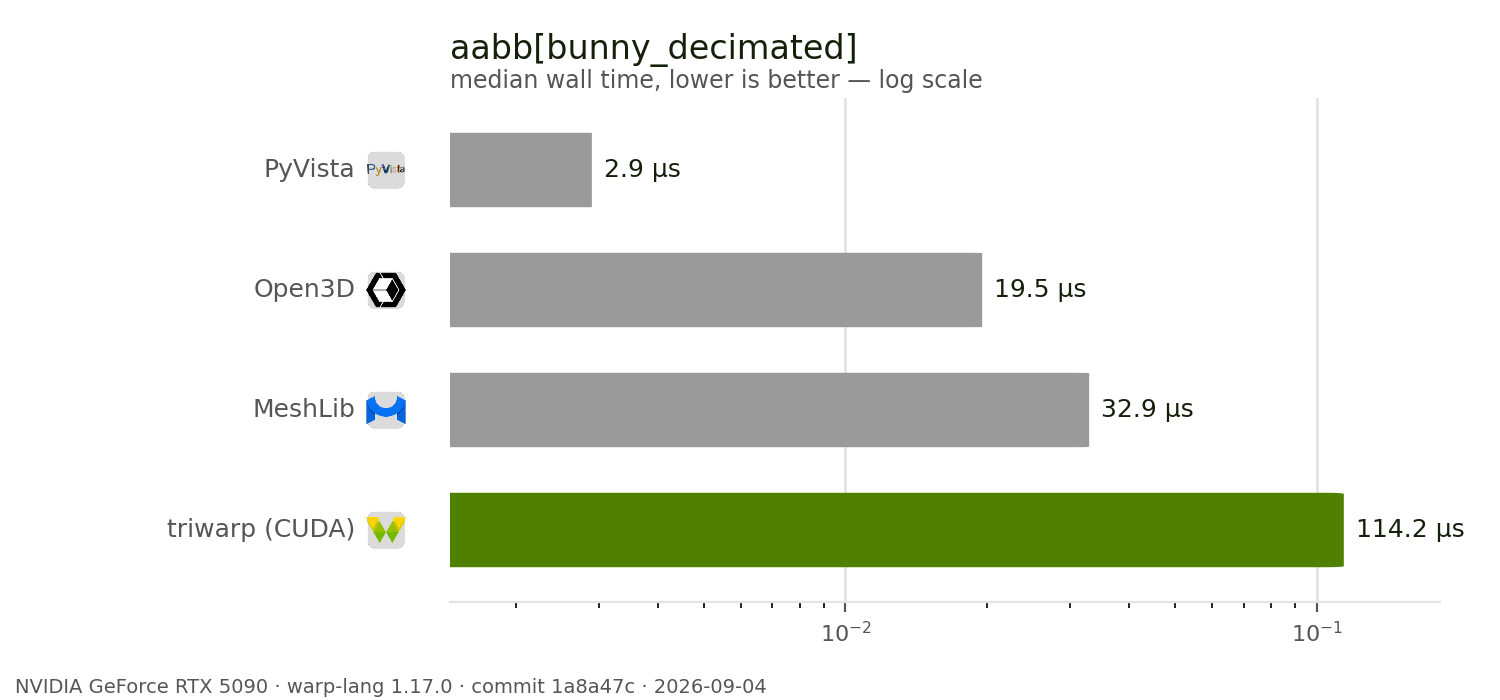
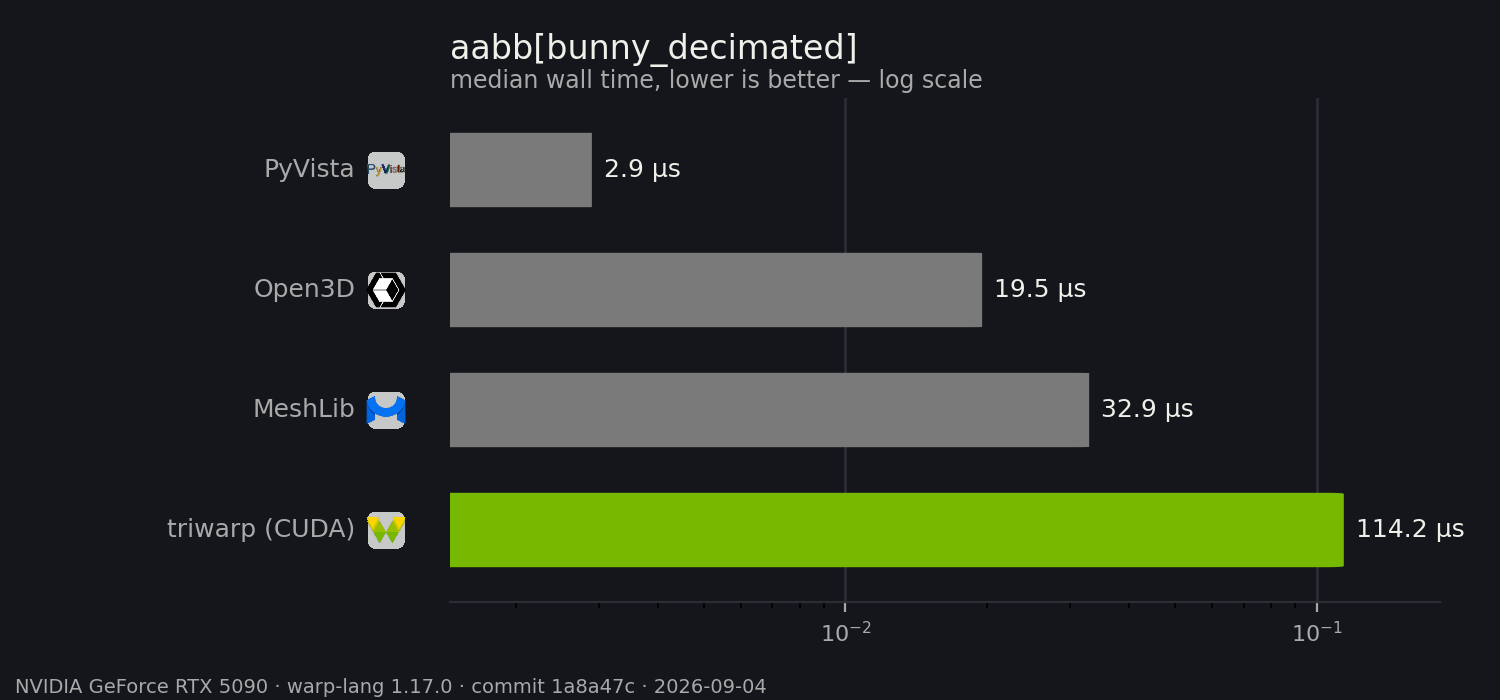
An axis-aligned bounding box is cheap enough on every library here that this cell is really a measurement of fixed per-call overhead rather than of any algorithm — worth keeping in mind before reading a large ratio on a very fast operation as more significant than it is.
Exact values
| Library | Median |
|---|---|
| PyVista | 2.9 µs |
| Open3D | 19.5 µs |
| MeshLib | 32.9 µs |
| triwarp (CUDA) | 114.2 µs |
Generated on an NVIDIA GeForce RTX 5090, warp-lang 1.17.0, from a benchmark run at commit
1a8a47c (2026-09-04). Numbers on this page are refreshed at release time, not continuously — see
Performance for how to read a speed claim, and the reproduce command above to
check any of these yourself against current code.